* denotes equal contribution
2026
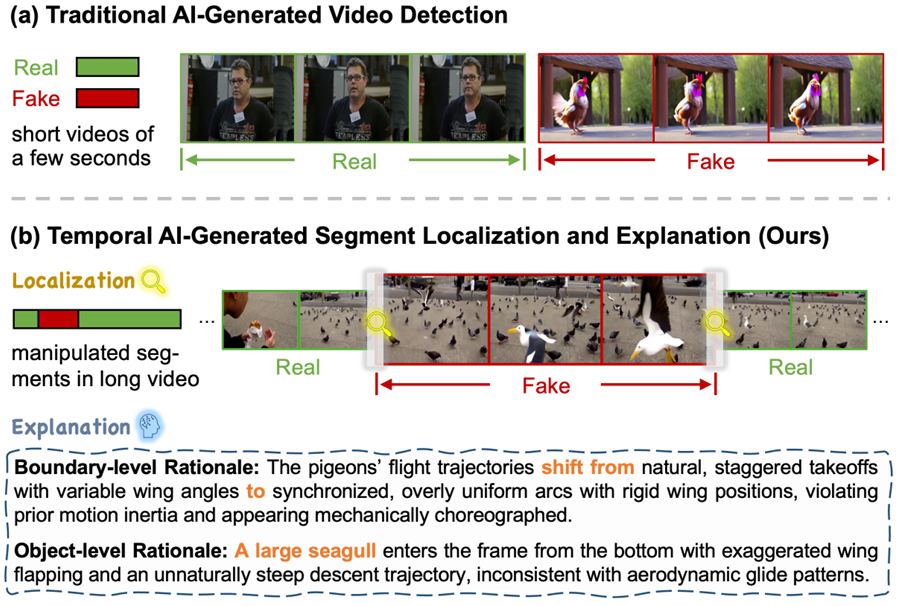
Explainable Forensics of Manipulated Segments in Untrimmed Long Videos
Y. Feng*, J. Li*, Q. Lu*, W. Ji, J. Zhang, F. Shen, X. Li, Y. Jia, Q. Chen, L. Wang, W. Li, J. Qin
International Conference on Machine Learning (ICML) 2026 CCF-A
We propose a framework for explainable forensics of AI-manipulated segments in untrimmed long videos, providing temporal localization and natural language explanations.
Explainable Forensics of Manipulated Segments in Untrimmed Long Videos
Y. Feng*, J. Li*, Q. Lu*, W. Ji, J. Zhang, F. Shen, X. Li, Y. Jia, Q. Chen, L. Wang, W. Li, J. Qin
International Conference on Machine Learning (ICML) 2026 CCF-A
We propose a framework for explainable forensics of AI-manipulated segments in untrimmed long videos, providing temporal localization and natural language explanations.
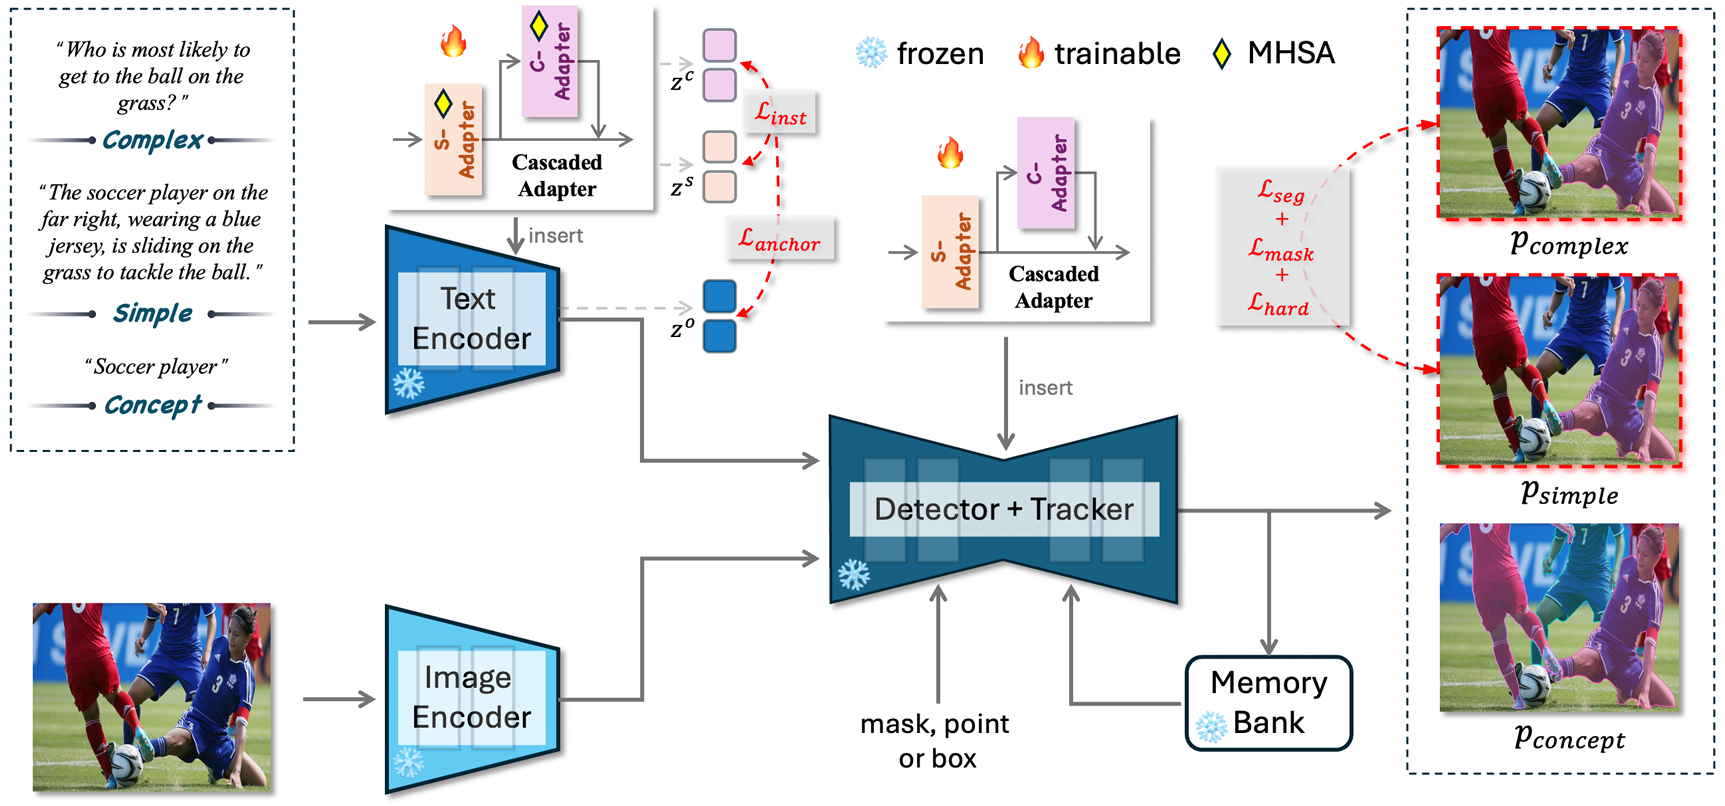
SAM3-I: Segment Anything with Instructions
J. Li*, Y. Feng*, Y. Guo*, J. Huang*, Y. Piao, Q. Bi, M. Zhang, X. Zhao, Q. Chen, S. Zou, W. Ji, H. Lu, L. Cheng
Annual Meeting of the Association for Computational Linguistics (ACL) 2026 CCF-A
We present SAM3-I, an instruction-guided segmentation model that extends SAM to handle diverse segmentation tasks through natural language instructions.
SAM3-I: Segment Anything with Instructions
J. Li*, Y. Feng*, Y. Guo*, J. Huang*, Y. Piao, Q. Bi, M. Zhang, X. Zhao, Q. Chen, S. Zou, W. Ji, H. Lu, L. Cheng
Annual Meeting of the Association for Computational Linguistics (ACL) 2026 CCF-A
We present SAM3-I, an instruction-guided segmentation model that extends SAM to handle diverse segmentation tasks through natural language instructions.
2025
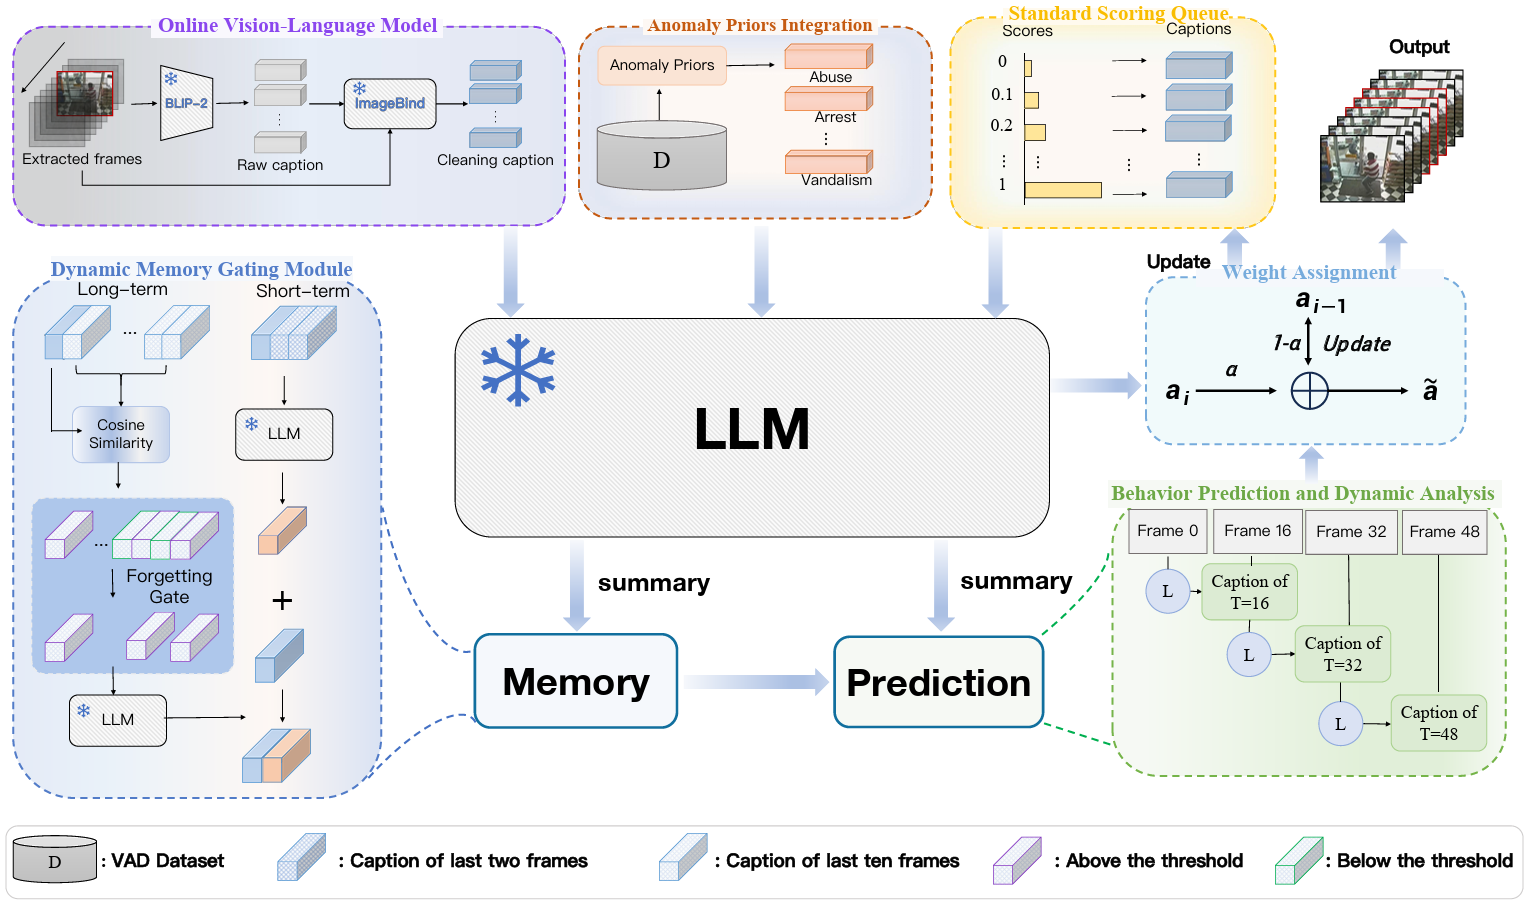
MoniTor: Exploiting Large Language Models with Instruction for Online Video Anomaly Detection
S. Yang*, Y. Feng*, Y. Liu, J. Zhang, J. Qin
Annual Conference on Neural Information Processing Systems (NeurIPS) 2025 CCF-A
We propose MoniTor, which leverages LLMs with instruction tuning for online video anomaly detection in streaming scenarios.
MoniTor: Exploiting Large Language Models with Instruction for Online Video Anomaly Detection
S. Yang*, Y. Feng*, Y. Liu, J. Zhang, J. Qin
Annual Conference on Neural Information Processing Systems (NeurIPS) 2025 CCF-A
We propose MoniTor, which leverages LLMs with instruction tuning for online video anomaly detection in streaming scenarios.
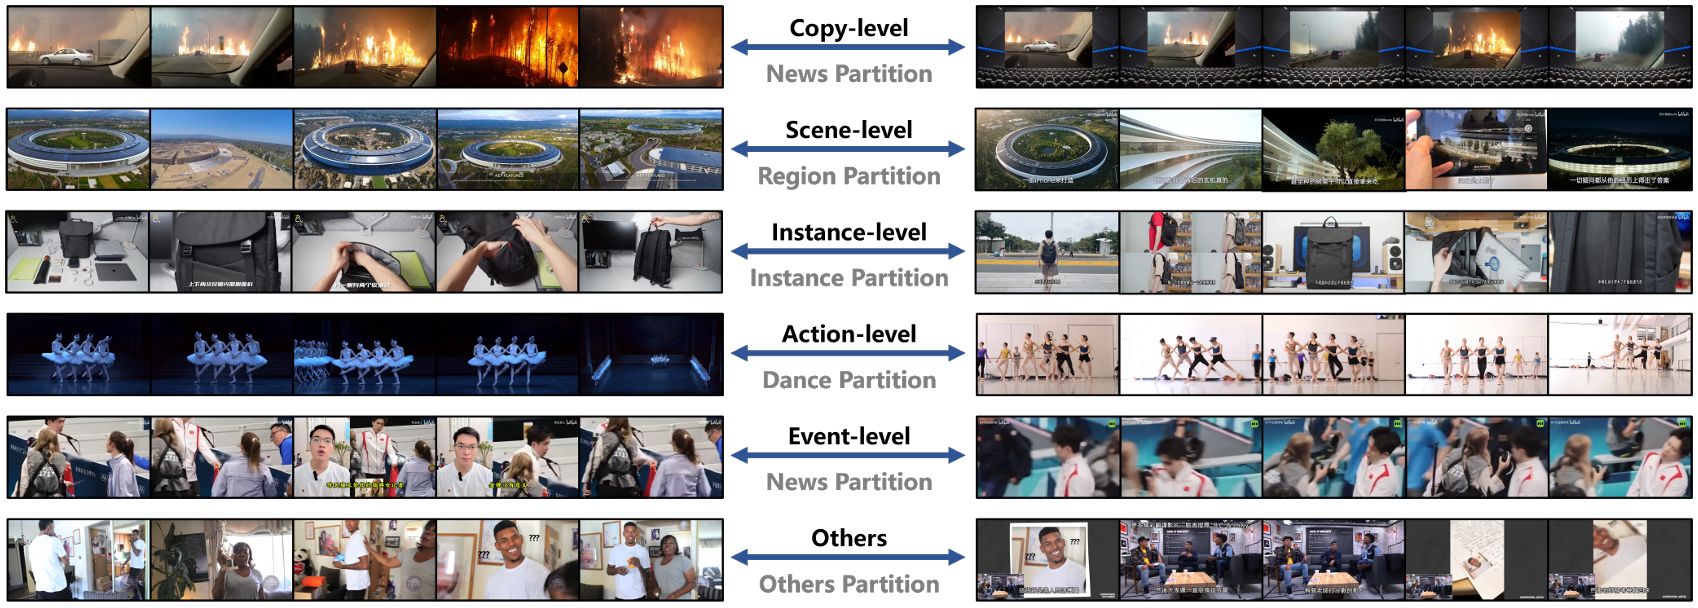
MUVR: A Multi-Modal Untrimmed Video Retrieval Benchmark with Multi-Level Visual Correspondence
Y. Feng, J. Hu, Q. Lu, J. Niu, L. Tan, S. Yuan, Z. Yan, Y. Jia, Q. He, S. Ge, E.Q. Chen, W. Li, L. Wang, J. Qin
Annual Conference on Neural Information Processing Systems (NeurIPS) 2025 CCF-A
We introduce MUVR, a large-scale benchmark for multi-modal untrimmed video retrieval with multi-level visual correspondence annotations.
MUVR: A Multi-Modal Untrimmed Video Retrieval Benchmark with Multi-Level Visual Correspondence
Y. Feng, J. Hu, Q. Lu, J. Niu, L. Tan, S. Yuan, Z. Yan, Y. Jia, Q. He, S. Ge, E.Q. Chen, W. Li, L. Wang, J. Qin
Annual Conference on Neural Information Processing Systems (NeurIPS) 2025 CCF-A
We introduce MUVR, a large-scale benchmark for multi-modal untrimmed video retrieval with multi-level visual correspondence annotations.
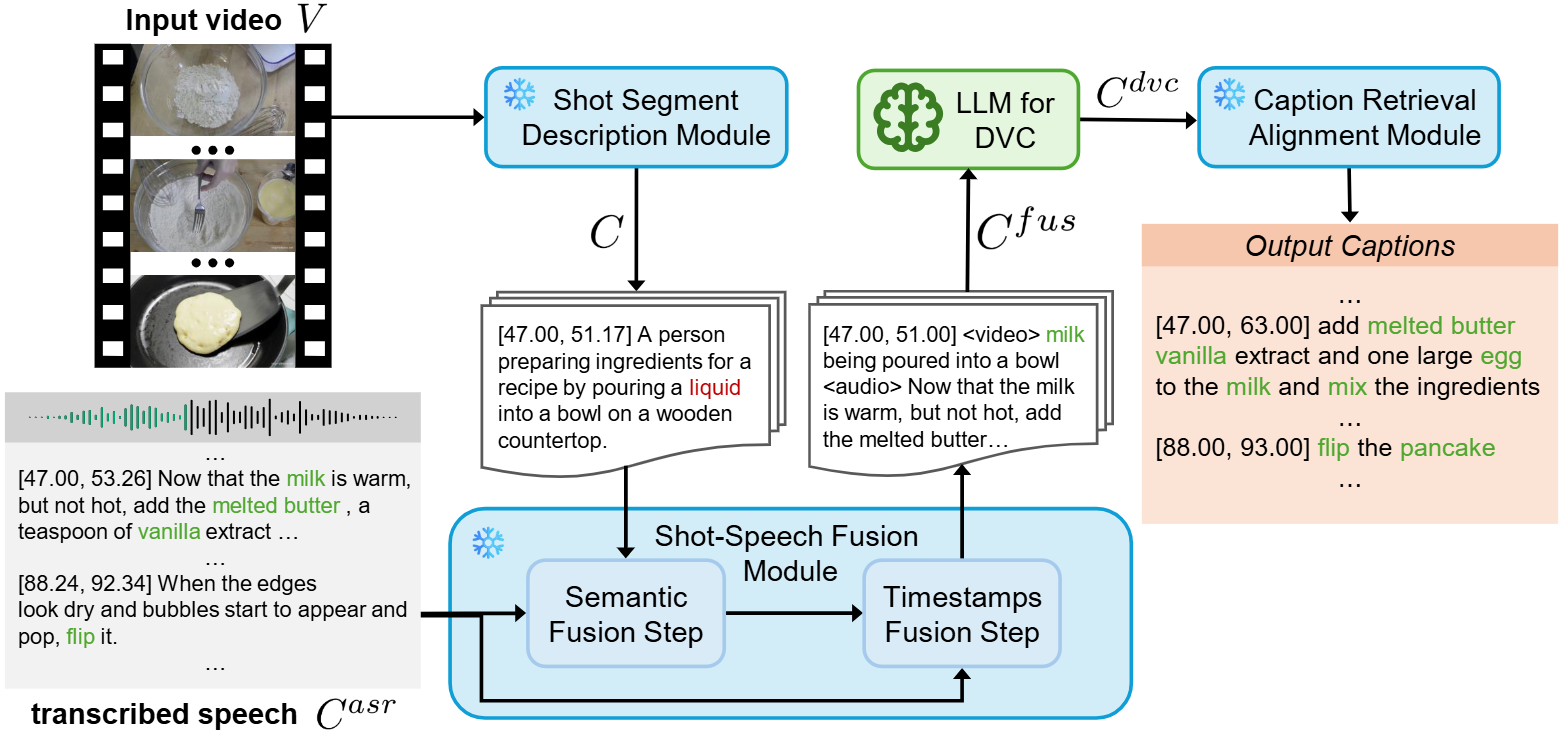
2024
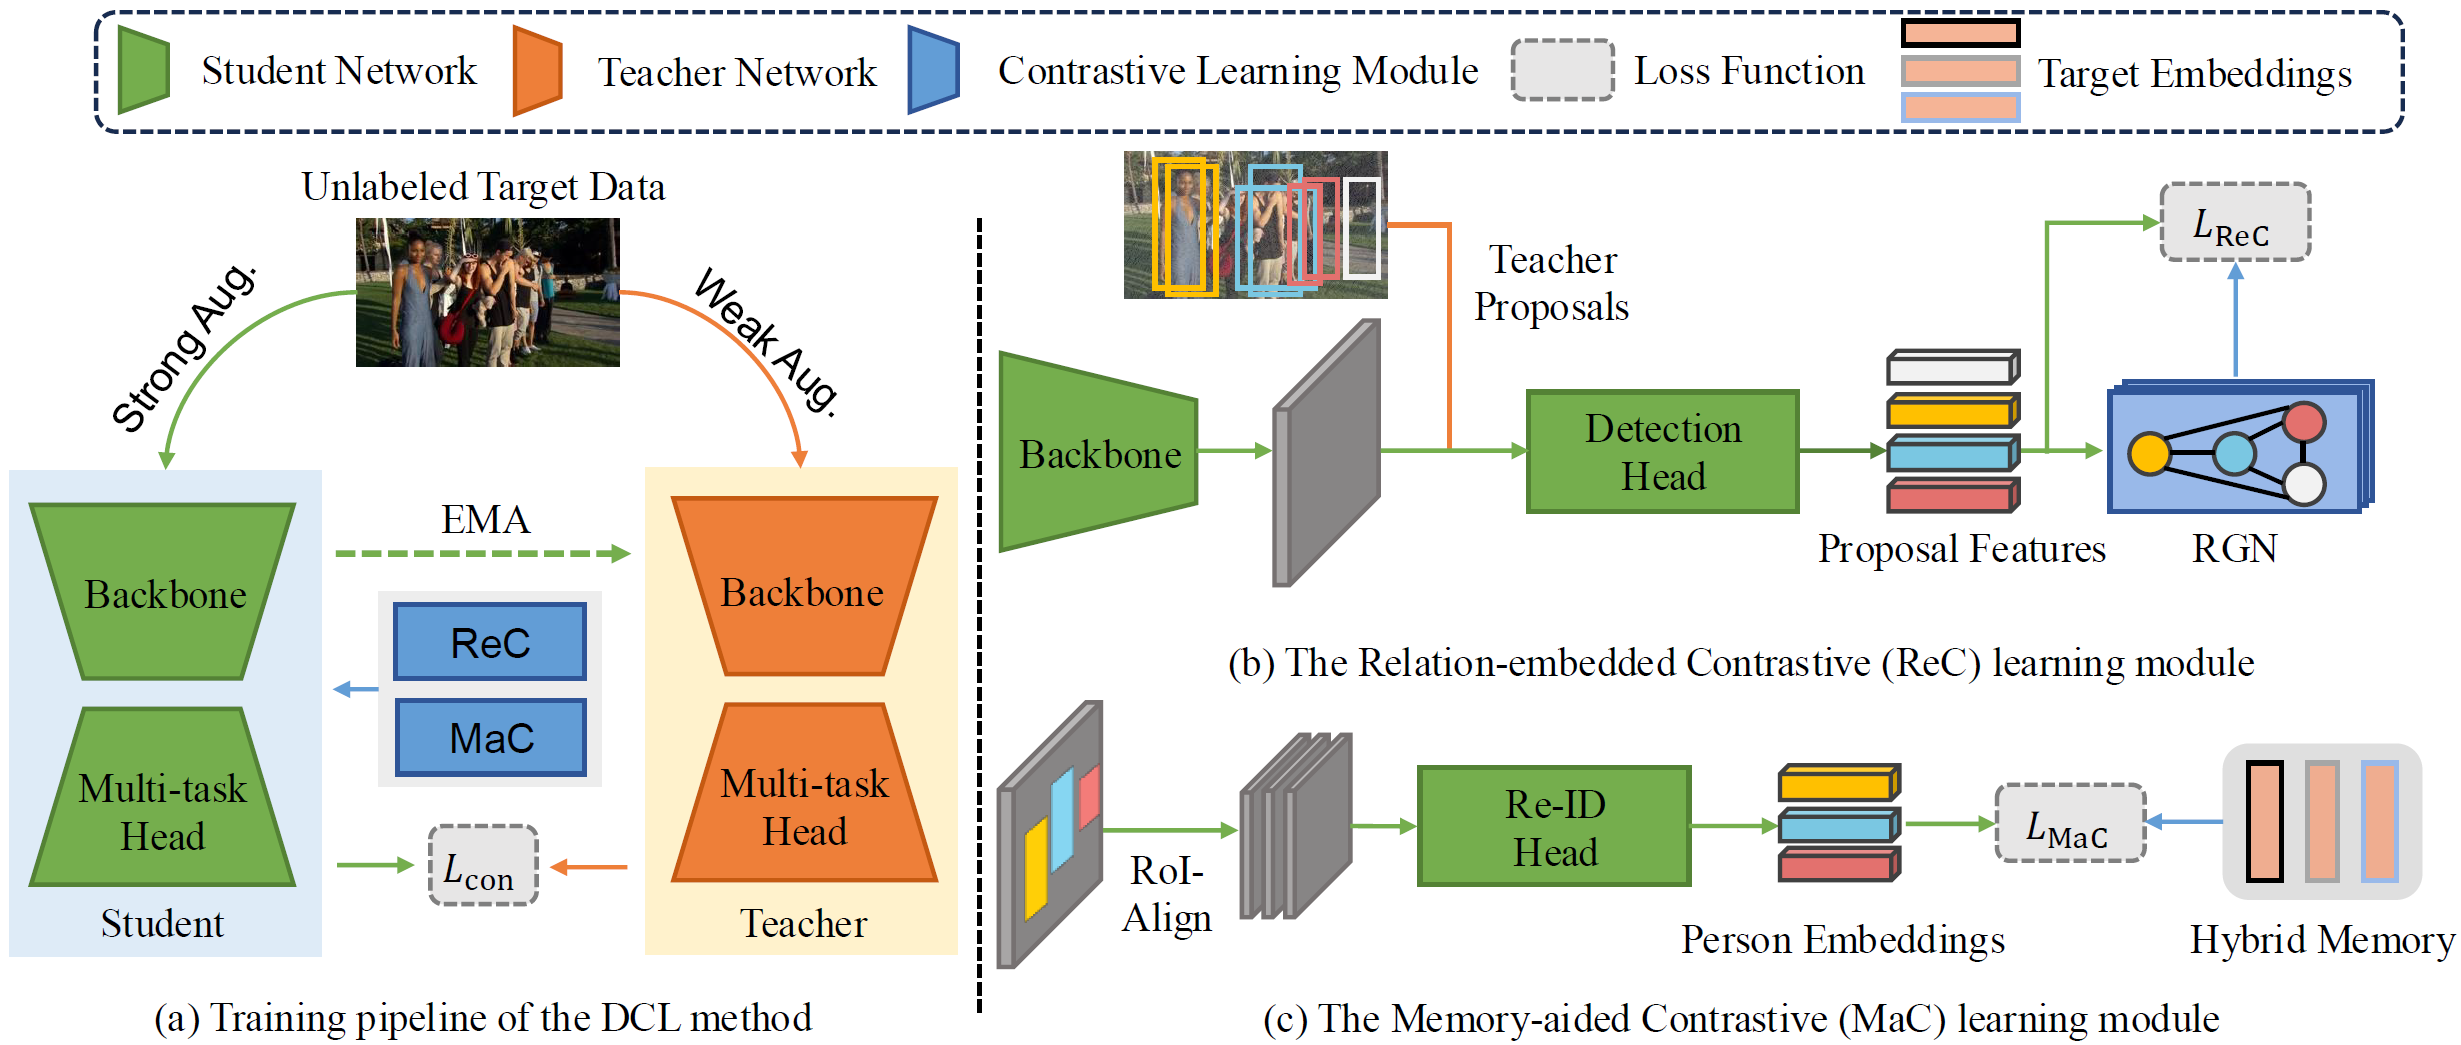
2023
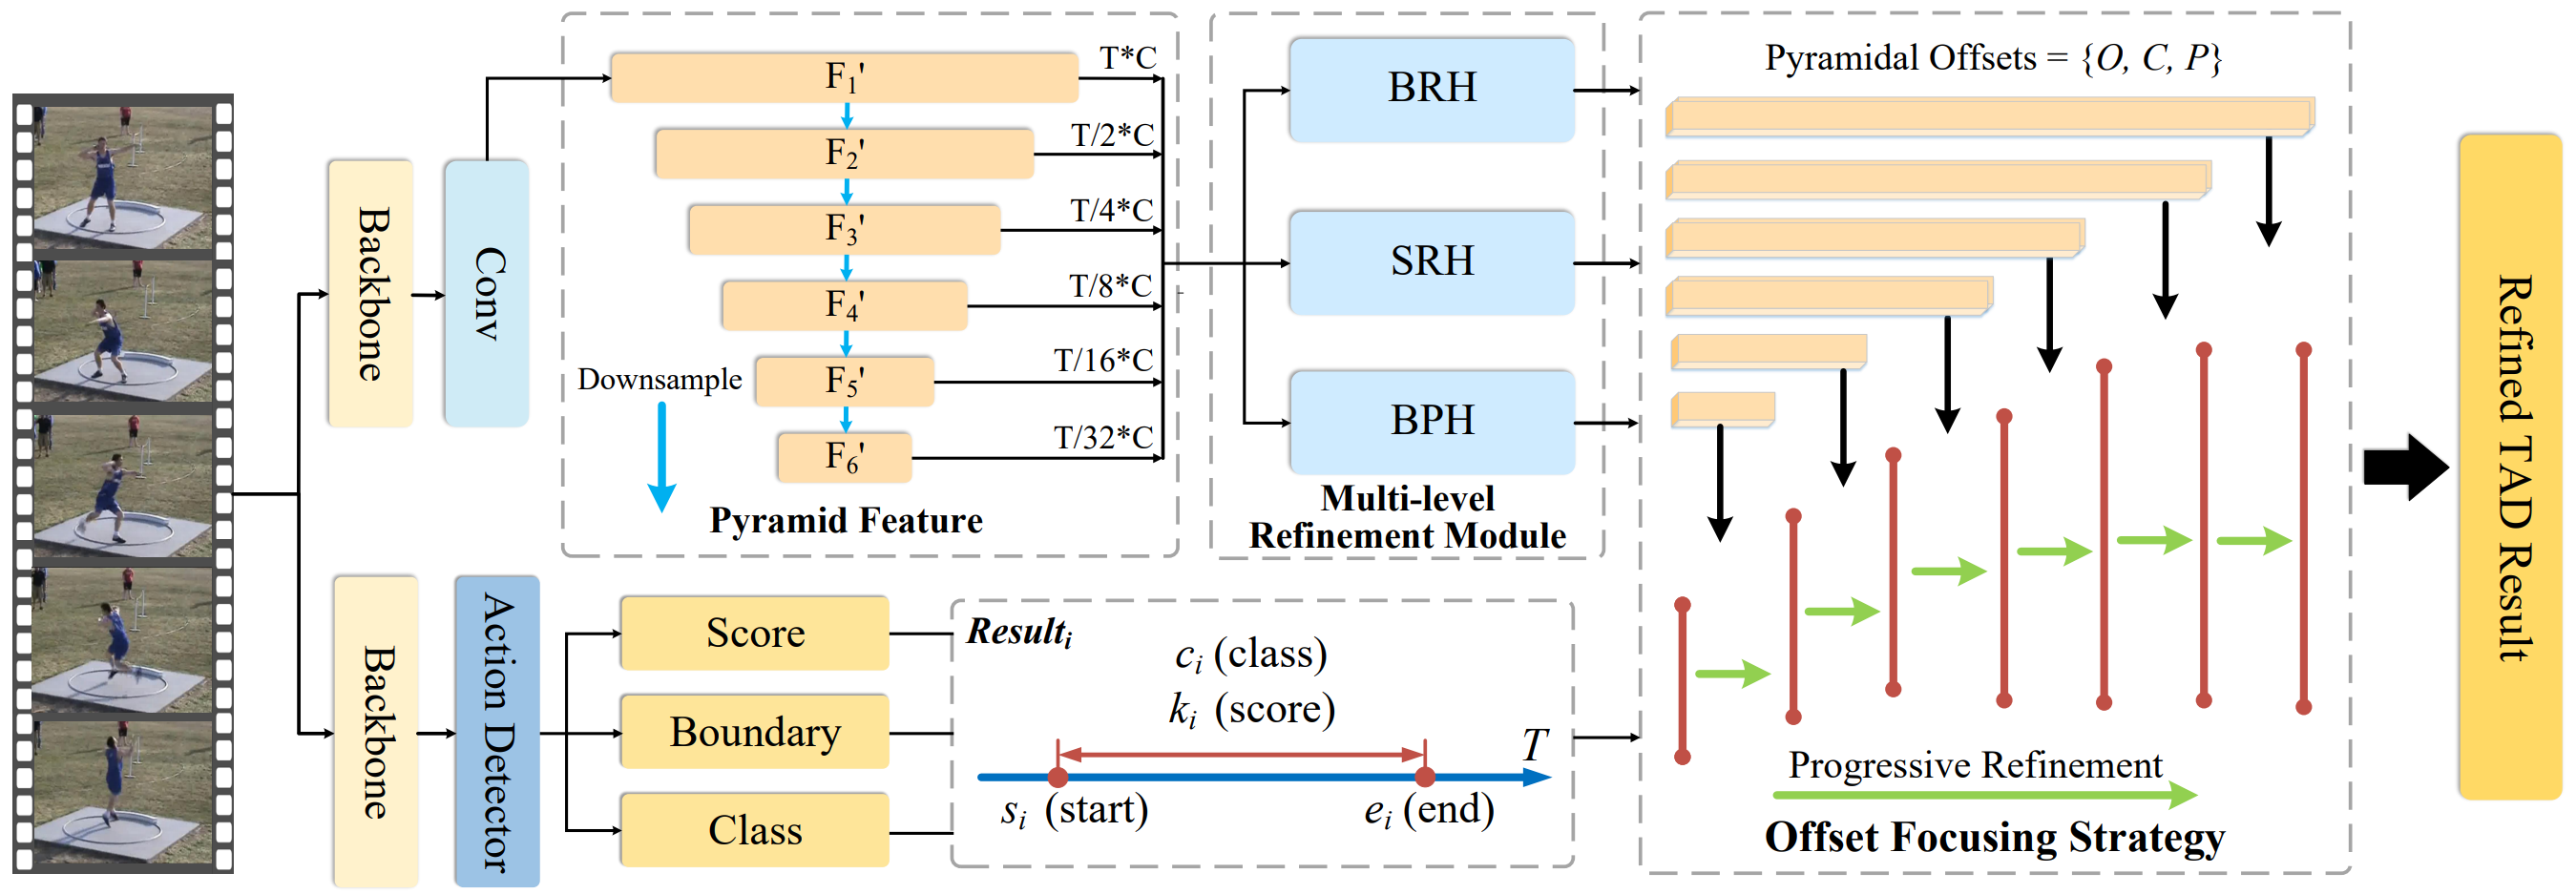
RefineTAD: Learning Proposal-free Refinement for Temporal Action Detection
Y. Feng, Z. Zhang, R. Quan, L. Wang, J. Qin
ACM International Conference on Multimedia (ACM MM) 2023 CCF-A Honorable Mention Award (Top 1‰)
We propose RefineTAD, a proposal-free framework for temporal action detection that achieves state-of-the-art performance with a novel refinement mechanism.
RefineTAD: Learning Proposal-free Refinement for Temporal Action Detection
Y. Feng, Z. Zhang, R. Quan, L. Wang, J. Qin
ACM International Conference on Multimedia (ACM MM) 2023 CCF-A Honorable Mention Award (Top 1‰)
We propose RefineTAD, a proposal-free framework for temporal action detection that achieves state-of-the-art performance with a novel refinement mechanism.